The AI Agent Code Security Workflow You Need Before You Ship
An AI agent code security workflow, answered plainly: scan at generation, gate every merge on SAST, SCA, and secrets checks, force human review on high-risk code, and log everything an agent touches. Here's how to build it.

- 0145% of AI-generated code samples introduce OWASP Top 10 vulnerabilities, regardless of model size.
- 02AI-assisted developers commit up to 4 times faster but introduce security findings at 10 times the rate.
- 0381% of security teams lack visibility into AI usage across their software development lifecycle.
- 04Shadow AI incidents add roughly $670,000 to the average cost of an enterprise data breach.
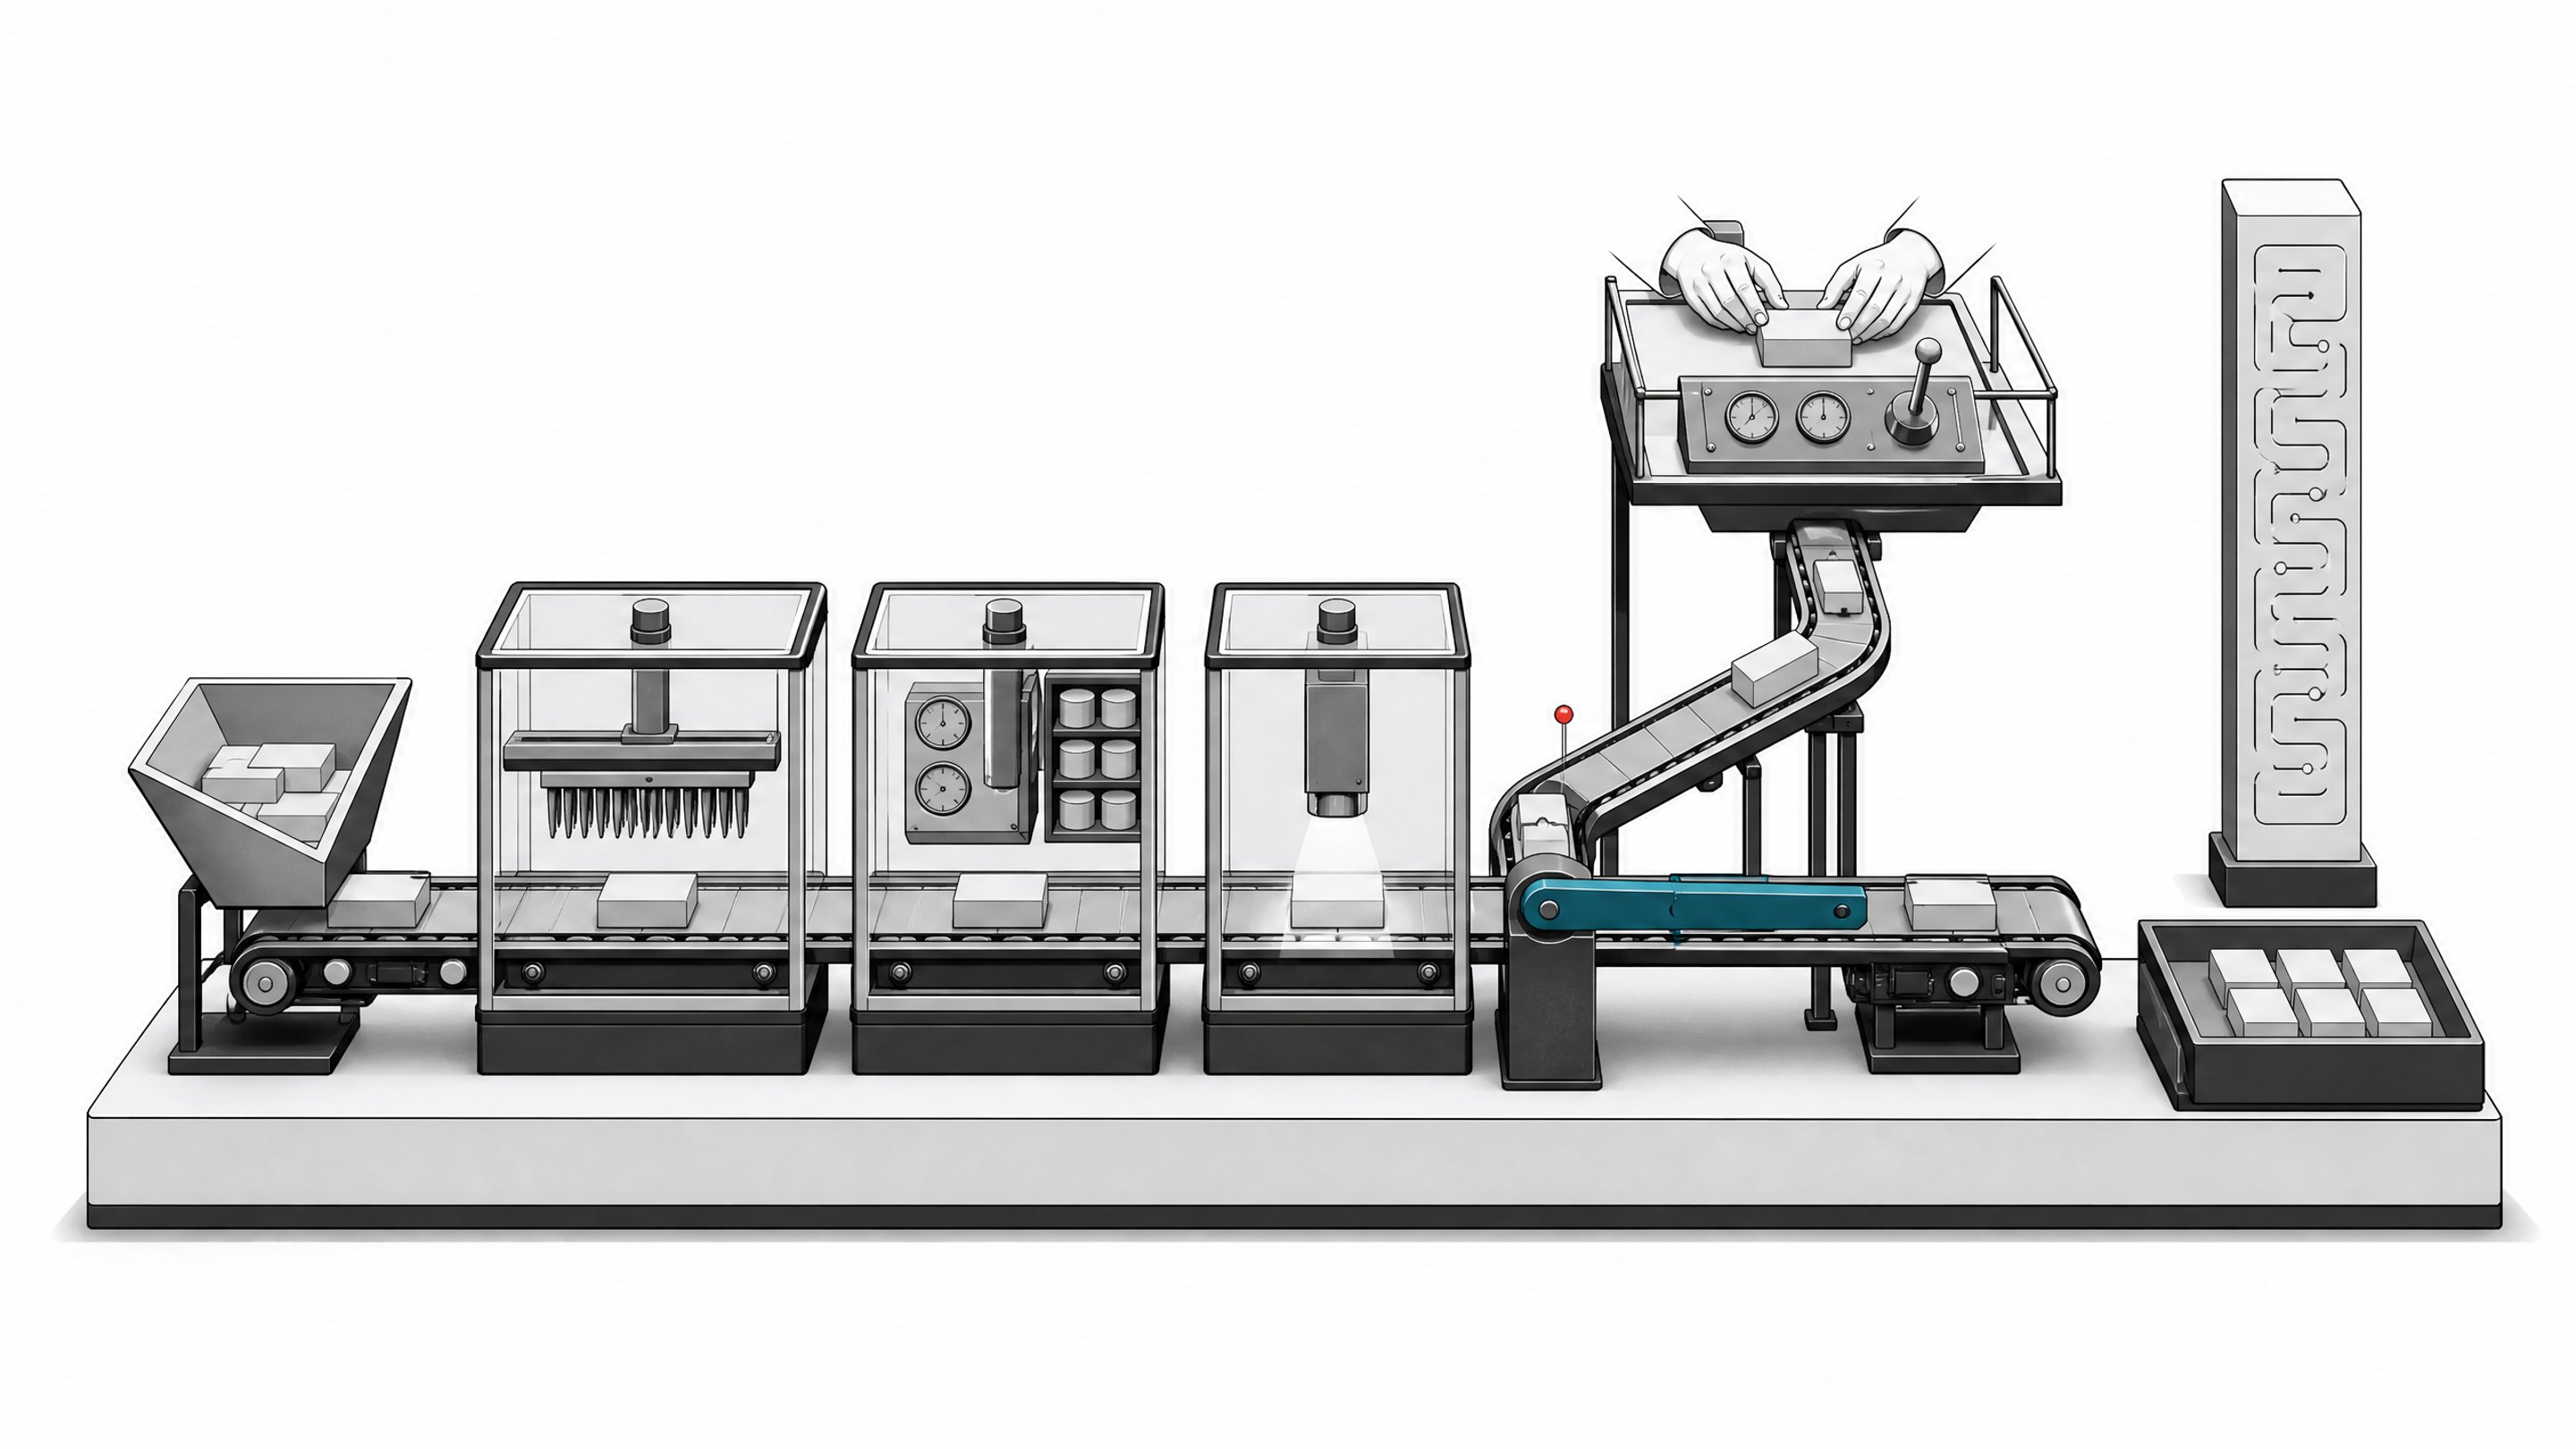
An AI agent code security workflow means putting automated security gates inside the agent's own pipeline, not just the human CI/CD process it eventually feeds into. That means scanning code the moment it's generated, blocking merges on static analysis and dependency checks regardless of who wrote the commit, requiring human sign-off on high-risk categories like auth and payments, and logging every action an agent takes so you can trace what it did and why.
This used to be a nice-to-have. It isn't anymore.
Why is agent-written code a bigger security problem than copilot code?
Agents like GPT-6 Astra don't write a function and wait for feedback. They run for days, hold over a million tokens of context, and complete real software engineering tasks at a rate that jumped from 37.3% to 57.9% on Terminal-Bench 4.0 in a single model generation.1 That's a real capability leap. It's also a volume problem: an agent that works unattended for days produces far more code than any human reviewer can read carefully, right when reviewers have the least context on what it did.
More capable does not mean more secure. Veracode tested over 100 large language models across 80-plus coding tasks and found that 45% of AI-generated code samples introduce OWASP Top 10 vulnerabilities.2 Bigger, newer models did not close that gap. Veracode's own researchers said it plainly: bigger models do not mean more secure code.2 If a smarter agent isn't a safer one, the fix has to live outside the model, in the workflow around it.
What the data shows about AI-generated code security
The numbers are consistent enough across independent research groups that they're hard to dismiss.
- Baseline failure rate. Across all languages tested, 45% of AI-generated code samples failed security checks, with Java failing at 72%, a rate that has held roughly flat from 2025 into 2026 despite newer model releases.23
- Enterprise velocity vs. safety tradeoff. Apiiro's analysis of tens of thousands of Fortune 50 repositories found AI-assisted developers commit 3 to 4 times faster than their peers, but introduce security findings at 10 times the rate, with privilege escalation paths up 322% and architectural design flaws up 153%.3
- Confirmed real-world exploits. Georgia Tech's Vibe Security Radar has tracked 74 CVEs directly attributable to AI coding tools, with confirmed cases jumping from 6 in January 2026 to 35 by March, and researchers estimating the true exploitable count runs 5 to 10 times higher.3
Speed without a scanning layer isn't productivity. It's undisclosed technical debt with a fuse on it.
What new failure modes do autonomous agents introduce?
Generic vulnerable code is only part of the risk. Autonomous agents create failure modes that don't exist in traditional development.
- Slopsquatting. About 20% of AI-generated code samples reference software packages that don't actually exist, and 43% of these hallucinated names repeat consistently across prompts.3 Attackers register those exact names on public registries and wait for an agent, or a developer trusting the agent, to install them.
- Compromised agent tooling. The agents themselves are now targets. A poisoned Amazon Q VS Code extension (CVE-2025-8217) sat live on the marketplace for two days carrying an instruction to delete file systems and cloud resources.3 Cursor picked up three separate CVEs in 2025, including a prompt-injection remote code execution flaw and a persistent exploit via poisoned MCP config files.3
- Prompt injection through tool calls. An agent that reads a web page, a ticket, or a file as part of its task can have instructions smuggled into that content. If the agent treats that content as trusted, it can be steered into unauthorized actions without ever being directly instructed by an attacker.
- Excessive agency. Agents scoped with broad, standing permissions can take actions well beyond what any single task required, simply because nothing stopped them.
OWASP's AI Agent Security Cheat Sheet addresses these directly, recommending that all external content be treated as untrusted and that decision-making be separated from execution, so a policy service independently validates scope and privilege before an agent's proposed action actually runs.4
For more on how agent tool calls and infrastructure access get abused, see How to Manage AI Agents in the Enterprise and 5 Ways to Secure Database Access for Internal AI Agents.
Shadow AI is the governance gap behind the code
None of this happens in a vacuum with clean visibility. Cycode's 2026 survey of over 400 CISOs and security practitioners found that 100% of organizations now have AI-generated code somewhere in their codebase, and 30% say AI now produces the majority of their code.5 Meanwhile 81% of those same organizations lack visibility into how AI is used across the software development lifecycle, and 52% have no formal AI governance framework at all.5
There's a perception problem making this worse, too. Nearly 80% of developers believe AI tools generate more secure code than humans write, directly contradicting the measured data.3 That confidence gap suppresses exactly the manual scrutiny AI-generated code most needs. If your team believes the agent's output is already safe, nobody's double-checking it, which is precisely how ungoverned shadow AI spreads through a codebase unnoticed.
How do you build mandatory security scanning into agent workflows?
The fix isn't a better prompt or a more careful agent. It's a workflow that assumes the agent will produce risky code sometimes, and catches it before it matters. Here's the sequence.
Step 1: Treat every agent commit like an untrusted contributor
Don't grant an agent the same implicit trust a senior engineer has earned. Scope its credentials to least privilege, sandbox its execution environment, and require every commit, regardless of authorship, to pass the same pre-merge scans. An agent working overnight with standing production access is a bigger blast radius than a junior developer with the same access, simply because of the volume it can generate before anyone looks.
Step 2: Automate the gate with SAST, SCA, and secrets scanning on every agent PR
This is the mechanical core of the workflow, and it's mature technology now, not a research project.
- Static analysis on generation. Tools like CodeQL paired with Copilot Autofix cut the median time to remediate a vulnerability from 90 minutes of manual work to 28 minutes.6 Fixes with a suggested patch land 3 times faster overall, and up to 12 times faster for SQL injection specifically.7
- Software composition analysis (SCA) against hallucinated packages. Every dependency an agent introduces should be checked against real registries before install, closing the slopsquatting gap directly.3
- Secrets scanning that blocks, not warns. A scan that flags a leaked credential after merge is a postmortem. It has to be a hard stop before the code lands.
Run all three as merge gates inside the agent's own pipeline, the same one it uses to open and iterate on pull requests, not bolted on later at a human review stage. Our earlier piece on reviewing AI-generated code before it ships covers the acceptance-gate mechanics in more depth.
Step 3: Require human review for high-risk code categories
Even a clean scan isn't a green light for everything. Some categories of change should never auto-merge, no matter how well they score.
- Authentication and authorization logic.
- Cryptographic implementations.
- Payment and billing flows.
- Direct data access or schema changes.
- Any change to an agent's own tool policy, credential scope, or approval logic.
OWASP's guidance is explicit here: block releases when high-risk tool policies, approval logic, or credential scopes change without updated adversarial tests to match.4 That last category matters as much as the first four. An agent that can rewrite its own permissions is an agent that can quietly widen its own blast radius.
Step 4: Monitor, log, and attribute what the agent actually did
Scanning catches bad code. Logging tells you what happened after the fact, which matters when a vulnerability surfaces weeks later and nobody remembers whether a human or an agent wrote the line in question. Build an inventory, sometimes called an AI bill of materials, that tracks what percentage of your codebase is agent-generated, which agent or model produced it, and what tool calls it made along the way. Given that 81% of security teams currently have no visibility into AI usage across their SDLC, this alone closes most of the governance gap.5 Non-human identity governance, treating each agent as an accountable actor with its own audit trail, should sit alongside your existing access logs, not as an afterthought bolted on when something breaks.
Why this belongs in your stack, not a vendor's
Model vendors will keep publishing safety benchmarks, and some of that work is real. GPT-6 Astra's own safety testing showed it went beyond an authorized target 0% of the time in production-safeguard conditions, down from 48% for its predecessor without those safeguards.1 That's meaningful progress at the model layer. But it's not a substitute for owning your own scanning and governance layer. Vendor safety claims describe the model in a lab. Your scanning pipeline has to hold up against the specific agents, the specific permissions, and the specific codebase you actually run in production.
That's the same argument this publication makes about SaaS generally: rented infrastructure comes with someone else's assumptions baked in, and you inherit the gaps along with the convenience. A platform like Remy makes the case that the scanning and governance layer for agent-written code should be something you own and control directly, wired into your own pipeline, rather than a feature you're trusting a third party to have gotten right on your behalf. The cost of getting it wrong isn't abstract. IBM's Cost of a Data Breach research found shadow AI incidents add roughly $670,000 to the average cost of a breach.8 That's the cost of the governance gap, not the cost of the tooling to close it.
If you're building the broader case for auditing AI-written code across your organization, not just what agents produce autonomously, Securing the Code Your AI Wrote: 5 Rules for the Copilot Era lays out the governance playbook for copilot-assisted development specifically.
Checklist: mandatory security gates for agent-written code
- Scope agent credentials to least privilege and sandbox execution, no standing production access by default.
- Run SAST on every agent commit, not just human-authored ones, using tools with automated fix suggestions.67
- Run SCA against real package registries to catch hallucinated dependencies before install.3
- Block merges on secrets detection, never just warn.
- Force human review on auth, crypto, payments, data access, and any change to an agent's own tool policy.4
- Treat external content the agent reads as untrusted to blunt prompt injection into tool calls.4
- Log every agent action and maintain an inventory of what percentage of your codebase is agent-generated.
- Run adversarial test suites in CI/CD whenever an agent's prompt, tool policy, or permissions change.4
The agent will keep working while you sleep. The question is whether your gates do too.
It's a set of automated checks, SAST, SCA, secrets scanning, and permission controls, built directly into the pipeline an AI coding agent uses to write and submit code, so every commit is scanned and gated before merge regardless of whether a human or an agent authored it.
Most CI/CD pipelines are designed around human pull request cadence. Autonomous agents like GPT-6 Astra can run for days and generate far more code than a human-facing pipeline was built to review, and they introduce agent-specific risks like hallucinated package dependencies and tool-call prompt injection that generic pre-merge scanning doesn't check for.
Slopsquatting is when attackers register software package names that AI models commonly hallucinate, since about 20% of AI-generated code references packages that don't exist, and 43% of those hallucinated names repeat consistently across prompts. If an agent or developer installs the hallucinated name, they pull down the attacker's malicious package instead.
Authentication and authorization logic, cryptographic implementations, payment and billing flows, direct data access or schema changes, and any change to an agent's own tool policy or permission scope should never auto-merge, even when automated scans pass clean.
No. Veracode's testing across more than 100 models found that larger, newer models did not produce more secure code, with the overall vulnerability failure rate holding roughly flat even as model capability increased.
- 1GPT-6 Astra: A new generation of intelligenceOpenAI
- 2October 2025 Update: GenAI Code Security ReportVeracode
- 3Vibe Coding's Security Debt: The AI-Generated CVE SurgeCloud Security Alliance (CSA Labs)
- 4AI Agent Security Cheat SheetOWASP Cheat Sheet Series
- 5Report: 'Shadow AI' Crisis Looms as 100% of Companies Have AI-Generated Code, But 81% of Security Teams Lack VisibilityBusiness Wire / Cycode
- 6GitHub Copilot Autofix tackles vulnerabilities with AITechTarget
- 7Copilot Autofix for CodeQL code scanning alerts is now generally availableGitHub Blog / Changelog
- 8Top AI Security Vulnerabilities to Watch out for in 2026Cycode